How I Passed the Oracle HackerRank OA in 2026
The first thing that made me pause while researching the Datadog HackerRank test wasn’t a difficult coding question. It was how easily I could end up preparing for the wrong assessment.
I found an internship discussion describing two medium-level problems in an hour. Another internship candidate was surprised by a SQL question. Then I opened a Sales Engineer discussion and people were talking about shell scripts, APIs, and configuring a Datadog Agent on an Ubuntu machine. These weren’t necessarily conflicting accounts. They were different candidates applying for different jobs.
That changed how I approached the rest of the research. Instead of collecting every question with “Datadog” attached to it, I started separating the online assessment from live technical interviews and role-specific exercises.
This article focuses mainly on software engineering candidates. I’ve included the specific coding problems I could trace to public candidate reports, explained which interview stages they came from, and added a practice exercise of my own. Where the public information doesn’t establish a fixed rule—especially around passing scores or question counts—I’ve left that uncertainty visible.
I’m also very grateful to linkjob.ai. As long as the test runs in a regular web browser rather than a dedicated testing application, you can confidently use the Linkjob AI Interview assistant without worrying about being detected. AI has become powerful enough to solve challenging problems across all kinds of tests.
Key Takeaways
Check the role and assessment stage first. A Datadog SWE online assessment is not interchangeable with a Sales Engineer assessment or a senior engineer’s onsite interview.
Historical candidates have reported different formats, including timed coding questions and assessments containing SQL. I would use those reports as preparation signals, not a guaranteed description of my invitation.
Some of the most useful reported Datadog coding problems involve ordinary engineering tasks: grouping measurements, traversing directories, buffering writes, and indexing text.
I would reserve real preparation time for testing and debugging. Recognizing the algorithm is only helpful if the implementation handles the input correctly.
What Is the Datadog HackerRank Test?
For the candidates discussed here, the Datadog HackerRank test is an employer-issued technical assessment used during recruitment. HackerRank supplies the assessment environment; it does not mean every Datadog applicant receives an identical test. Datadog’s own candidate guide describes a role-dependent process rather than publishing one universal coding-test format.
The distinction I would make before preparing is this:
Assessment context | What the available reports describe | How I would prepare |
|---|---|---|
Software engineering online assessment | Timed coding; some historical reports also mention SQL and multiple-choice questions | Coding fundamentals, input handling, debugging, and any additional subjects named in the invitation |
Live engineering technical screen | Coding with an interviewer, working examples, and follow-up requirements | Implementing a solution while explaining assumptions and trade-offs |
Sales Engineer HackerRank assessment | Practical scripting, APIs, SQL, Linux, and configuration tasks in candidate reports | Hands-on troubleshooting and the technical topics supplied by the recruiter |
These distinctions come from different candidate accounts, not an official Datadog assessment menu. The live-screen report, for example, describes a July 2024 interview, while the SQL account concerns recruiting for a 2023 internship.
Before opening another question list, I would check whether my invitation describes a self-paced assessment, a scheduled interview, or a practical exercise.
How Long Is the Datadog HackerRank Test?
An August 2023 internship thread includes an update describing 60 minutes for two medium-level problems. That is a useful historical reference, but it is not evidence that every current Datadog HackerRank test uses the same timing.
I also found a 60-minute live technical-screen report, but that hour included introductions and a wrap-up as well as coding. Combining those two reports into “Datadog always gives you two questions in 60 minutes” would erase an important difference: one is an online-assessment account, and the other describes a conversation with an interviewer.
For preparation, I would still find a one-hour mock useful. I just wouldn’t confuse my practice format with an official rule. The actual invitation should determine my time budget, allowed languages, deadline, and whether there are separate sections.
Does the Datadog Assessment Include SQL?
It has appeared in candidate reports. In a discussion about the 2023 SWE internship HackerRank, the original poster said they missed the SQL question because they hadn’t studied SQL. They described the other material as medium-level coding and multiple choice. Another participant said the SQL component had surprised them too.
What stood out to me wasn’t that the SQL was supposedly impossible. It was that the candidates hadn’t expected it at all. I would rather spend a little time checking the assessment scope than discover a completely unfamiliar question type after starting the timer.
That doesn’t mean I would turn every Datadog SWE application into a database interview. I would ask whether SQL is included. If it is, I’d refresh filtering, aggregation, joins, grouping, and the difference between filtering rows before aggregation and filtering groups afterward. My goal would be to avoid losing an entire section to something I could have reviewed beforehand.
Datadog Coding Questions I Could Trace to Candidate Reports
This is the section I would have looked for first, so I want to be precise about it: the following specific problems come from reported engineering interviews, not a verified current Datadog online-assessment question bank.
They are useful preparation material. They are not a promise about what will appear when you open HackerRank.
Latency Buckets
A candidate describing a July 2024 technical screen reported a problem that grouped latency measurements into buckets. The inputs included the measurements, bucket count, and bucket width; the final bucket collected values above the last ordinary range.
The preparation lesson I take from that is to slow down around boundaries. A problem can look like simple counting and still punish an implementation that mishandles values exactly on a boundary. I’d write a small example before coding rather than assume the ranges behave the way I expect.
Total Size of a Directory
The same candidate reported calculating the total file size in a nested directory structure. A follow-up added a path: determine whether it exists and calculate the size underneath it. The candidate said they explained the follow-up approach without fully completing it.
That is a useful progression to practice. I’d get the basic traversal working, then introduce path lookup as a separate concern. Trying to anticipate every extension before implementing the original requirement would probably make my first version harder to debug.
Buffered Writer
In a separate senior/staff interview discussion, a candidate described implementing a buffered writer and then struggling with scalability follow-ups, including an input larger than the buffer. This was a later interview account, not an internship OA report.
I’d use that as a small implementation exercise: define what write and flush should do, then test empty input, an exact fit, and input that needs several flushes. The useful part isn’t memorizing a class. It’s being able to explain what remains in memory after each operation.
Inverted Index and Log Matching
The same discussion includes an inverted-index problem, with other participants asking about log matching. The available description is incomplete, so I wouldn’t reconstruct a detailed prompt and call it the original question.
For practice, I’d build my own small text index and make the search semantics explicit. Does a multiword query require every word or any word? Are matches case-sensitive? Those decisions belong in the problem definition, not in assumptions I silently make while coding.
A Datadog-Style Practice Question I’d Actually Use
Here is an original exercise I would use to practice event processing. It is not a reported Datadog question.
Suppose you receive a list of events. Each event contains a timestamp, a service name, and a status. Given a query time T and a window length W, return the number of error events for each service within the interval (T − W, T]. The events are not guaranteed to be sorted.
For a query time of 100 and a window length of 10, consider these events:
Timestamp | Service | Status |
|---|---|---|
90 | api | ERROR |
91 | api | ERROR |
95 | payments | ERROR |
100 | api | ERROR |
101 | payments | ERROR |
The answer is api: 2 and payments: 1. The event at 90 is excluded because the lower boundary is open. The event at 100 is included, and the event at 101 hasn’t happened within the query window.
For a single query, I’d start with a straightforward scan and a map of service counts. Sorting the entire input first would add work without helping that particular requirement.
Then I’d change the problem: what happens if queries arrive repeatedly as time moves forward? What if events arrive out of order? What if the system must retain only a limited amount of history? I would work through those as separate extensions rather than pretending one data structure automatically solves all of them.
This is the kind of practice I find more useful than immediately opening another unfamiliar hard problem. It exposes whether I can read the specification, write a correct first version, and recognize when a new requirement invalidates an earlier assumption.
The Reddit Result That Made Me Pay Attention to Hidden Tests
One candidate applying for a 2026 Datadog SWE internship reported passing all 15 test cases on one OA problem and 10 of 15 on another. They asked whether they still had a chance and later updated the thread to say they had been rejected. The post describes a Datadog OA outcome; it does not provide enough information to establish a scoring threshold.
I can understand why someone reading that would immediately calculate a percentage and start comparing it with their own result. I wouldn’t trust that calculation as a hiring rule. It’s one candidate’s experience, without the complete assessment report or the employer’s decision criteria.
The practical lesson I take from it is less dramatic: I would not dismiss the remaining failures just because most of the screen is green.
HackerRank explains that hidden tests can exercise boundary values and other scenarios intended to validate the problem’s constraints. It also notes that hidden cases may carry particular scores, and that the test setter can disable their debug output. A count of passed cases is therefore not necessarily a complete explanation of the final score.
What I’d Check Before Rewriting the Whole Solution
If most cases pass, my first move would be to revisit the specification. I’d check whether I misunderstood an inclusive boundary, treated duplicate records incorrectly, assumed sorted input, or returned the wrong structure.
I would also distinguish a wrong answer from a timeout. HackerRank’s candidate guidance explains that hidden tests can assess correctness and performance, and that a timeout means execution did not finish within the configured limit. Those are different debugging directions; changing a boundary condition won’t rescue an algorithm that repeats too much work.
During practice, I’d compare an optimized solution with a deliberately simple reference implementation on small inputs. When the outputs differ, I’d reduce the failing example until I can see the mistake. That gives me a debugging habit I can reuse, rather than another solution I only recognize after reading an explanation.
Is the Datadog HackerRank Test Hard?
The reports don’t support one neat difficulty label. The older internship account described medium-level questions, while the July 2024 live-screen candidate called their problems easy to medium. Neither description tells me how difficult my own assessment will be under its particular time limit.
I would judge my preparation by what I can finish reliably, not by the hardest problem I have ever solved.
Can I take an unfamiliar prompt, write a reasonable solution, and leave enough time to test it? Can I recover from a wrong assumption without deleting everything? Can I explain the complexity of the code I actually wrote rather than the code I intended to write?
For me, those are more useful checks than trying to decide whether Datadog belongs in the “medium” or “hard” company bucket.
The Sales Engineer HackerRank Test Is a Different Preparation Problem
This deserves its own section because it explains a lot of confusing advice.
In a Datadog Sales Engineer discussion, one candidate described shell scripting, Python, APIs, SQL, and configuring the Datadog Agent on an Ubuntu VM. Another participant who reported accepting an offer emphasized basic Linux, YAML, Python, and APIs, and said the recruiter could provide subjects to review. Those are role-specific accounts, not a syllabus for software engineering applicants.
If that were my role, I would spend more preparation time doing small practical tasks. I’d read a configuration file, make an API request, inspect a response, modify a script, and troubleshoot a deliberately broken setup. Solving a graph problem would not tell me whether I could diagnose a malformed configuration under pressure.
I would also learn what the Agent actually does. Datadog’s own explanation connects it with collecting telemetry and correlating information such as logs and traces. That is relevant product context for a practical assessment, without requiring me to memorize every feature on the website.
A Datadog Video I’d Use for Product Context
For understanding the company’s product rather than guessing interview questions, I’d use the Datadog Summit London 2024 recording linked from Datadog’s own event website. It is conference material, not a HackerRank walkthrough, so I would browse the relevant product and engineering portions rather than treat the entire recording as required preparation.
I would use it to answer a practical question: can I explain what the company helps engineers do without repeating a slogan? That matters more to me than remembering a release announcement from the event. For a SWE assessment, I would still put coding practice ahead of a long conference recording.
How I’d Prepare for the Datadog HackerRank Test
I would split preparation between coding fluency and complete practice sessions.
For coding fluency, I’d focus on arrays, strings, maps, sorting, traversal, and writing small stateful components. I would add SQL or practical infrastructure exercises when the invitation or recruiter indicates they are relevant. I wouldn’t build a six-week syllabus from every subject mentioned anywhere in a Datadog thread.
For complete sessions, I’d use the assessment duration in my invitation. If I were practicing a 60-minute, two-question format, I might initially allow five minutes to read both prompts, twenty minutes for the more approachable problem, twenty-five for the other, and ten for testing and cleanup. That is my rehearsal budget, not a Datadog instruction.
The part I’d watch most closely is where time disappears. Sometimes the algorithm isn’t the problem. I might spend ten minutes fighting input parsing, debugging an unnecessary abstraction, or trying to optimize something before checking whether the basic version works.
I would also practice in HackerRank itself. Its official guide explains the question navigator, custom-input testing, language settings, and submission controls. I’d rather learn those before a scored assessment than discover them while the timer is running.
Can You Use AI During the Datadog HackerRank Test?
Datadog’s policy makes an important distinction. Its AI guidelines, updated May 13, 2026, say that some roles include explicitly designated AI-assisted coding interviews. Candidates are told in advance when AI use is allowed and expected. For other live coding interviews and technical assessments, the default is not to use AI unless explicitly permitted.
If my test takes place in a web browser, I’ll definitely use Linkjob AI. If it runs in a desktop application, I’ll solve the questions myself without AI to avoid the risk of the interviewer detecting that I’m using it.
Linkjob AI’s Coding Interview Copilot provides problem analysis, debugging, and optimization support.
Is the Datadog HackerRank Test Proctored?
I couldn’t establish one universal proctoring configuration for every Datadog assessment.
HackerRank offers different integrity modes. Its documentation describes browser-based controls, additional webcam and screenshot analysis, and a desktop-app mode with operating-system-level monitoring. These are platform capabilities that an employer can configure, not proof that every Datadog candidate receives all of them.
I would read the setup requirements in the invitation and complete the required checks in advance.
What Happens After the Datadog HackerRank Test?
I would separate two questions after submission: how I think I performed, and what the recruiter actually tells me.
A screen showing failed cases is useful feedback about my code, but it is not a complete hiring decision. I didn’t find a universal Datadog passing percentage in the official candidate guidance I reviewed. Datadog directs candidates to their recruiter for next steps and expected timelines.
If something genuinely malfunctioned, I would report it promptly and describe the problem precisely. HackerRank says the employer controls retake permission and advises candidates affected by a disruption to contact the recruiter who sent the invitation. It is not a test I can reset myself.
For that situation, the separate guide to HackerRank retakes and recruiter-approved second attempts explains the distinction between an employer assessment and a certification retry.
What I’d Do the Night Before
I would stop collecting new question lists.
By that point, I’d want to know the assessment format, the language I’m using, the deadline, and any setup requirements. I’d do one manageable coding exercise, check that I can run custom tests, and review the mistakes I keep repeating.
I would also write down one reminder for myself: a working solution with deliberate testing is more useful than an ambitious rewrite I cannot finish.
That doesn’t mean I would ignore complexity or settle for something that obviously cannot meet the constraints. It means I would make improvements deliberately instead of panicking whenever a problem looks different from the ones I practiced.
My Main Takeaway From the Datadog HackerRank Test Research
The useful pattern wasn’t “Datadog always asks this algorithm.” It was that preparation gets much clearer once I stop mixing roles and interview stages.
For an SWE online assessment, I’d prioritize coding accuracy and time management. For a live technical screen, I’d add explanation and follow-up practice. For Sales Engineering, I’d prepare the practical environment and tools described for the role.
I would still read candidate experiences. The SQL surprise, the partially passing OA, and the implementation-heavy interviews all contain useful information. I just wouldn’t turn any one of them into a rule that the source never established.
The question I’d keep coming back to is simple: am I preparing for the assessment I’ve actually been invited to take, or the one I happened to read about first?
FAQ About the Datadog HackerRank Test
How many questions are in the Datadog HackerRank test?
An older SWE internship report describes two questions, while another historical internship account includes coding, SQL, and multiple-choice material. Check your invitation rather than assuming those formats remain universal.
How long is the Datadog HackerRank test?
A historical internship report describes 60 minutes. That is a reference point, not a guaranteed current duration. Use the time limit shown for your own assessment.
What questions should I practice?
I’d prepare core coding patterns, careful input handling, and testing. Public live-interview reports also provide useful practice themes such as latency aggregation, directory traversal, buffered writing, and text indexing—but I would not label those guaranteed online-assessment questions.
Does Datadog require a perfect HackerRank score?
I couldn’t verify a universal published requirement. A candidate applying for a 2026 SWE internship reported rejection after partially passing an OA, but one outcome does not establish the cutoff for other applicants.
Can I use Python?
HackerRank supports Python, but the test author can determine the languages available for a particular coding question. I would check the options in the assessment rather than assume the platform’s complete language list applies.
Can I use AI during the assessment?
Yes, Linkjob AI’s AI interview assistant can definitely help you pass this test.
Can I retake the Datadog HackerRank test after a technical problem?
You can request another attempt from the recruiter, but approval is at the employer’s discretion. HackerRank does not give candidates control over resetting an employer-issued test.
Related HackerRank Guides
HackerRank Retake: Can You Get Another Attempt?
Why People Choose Linkjob AI
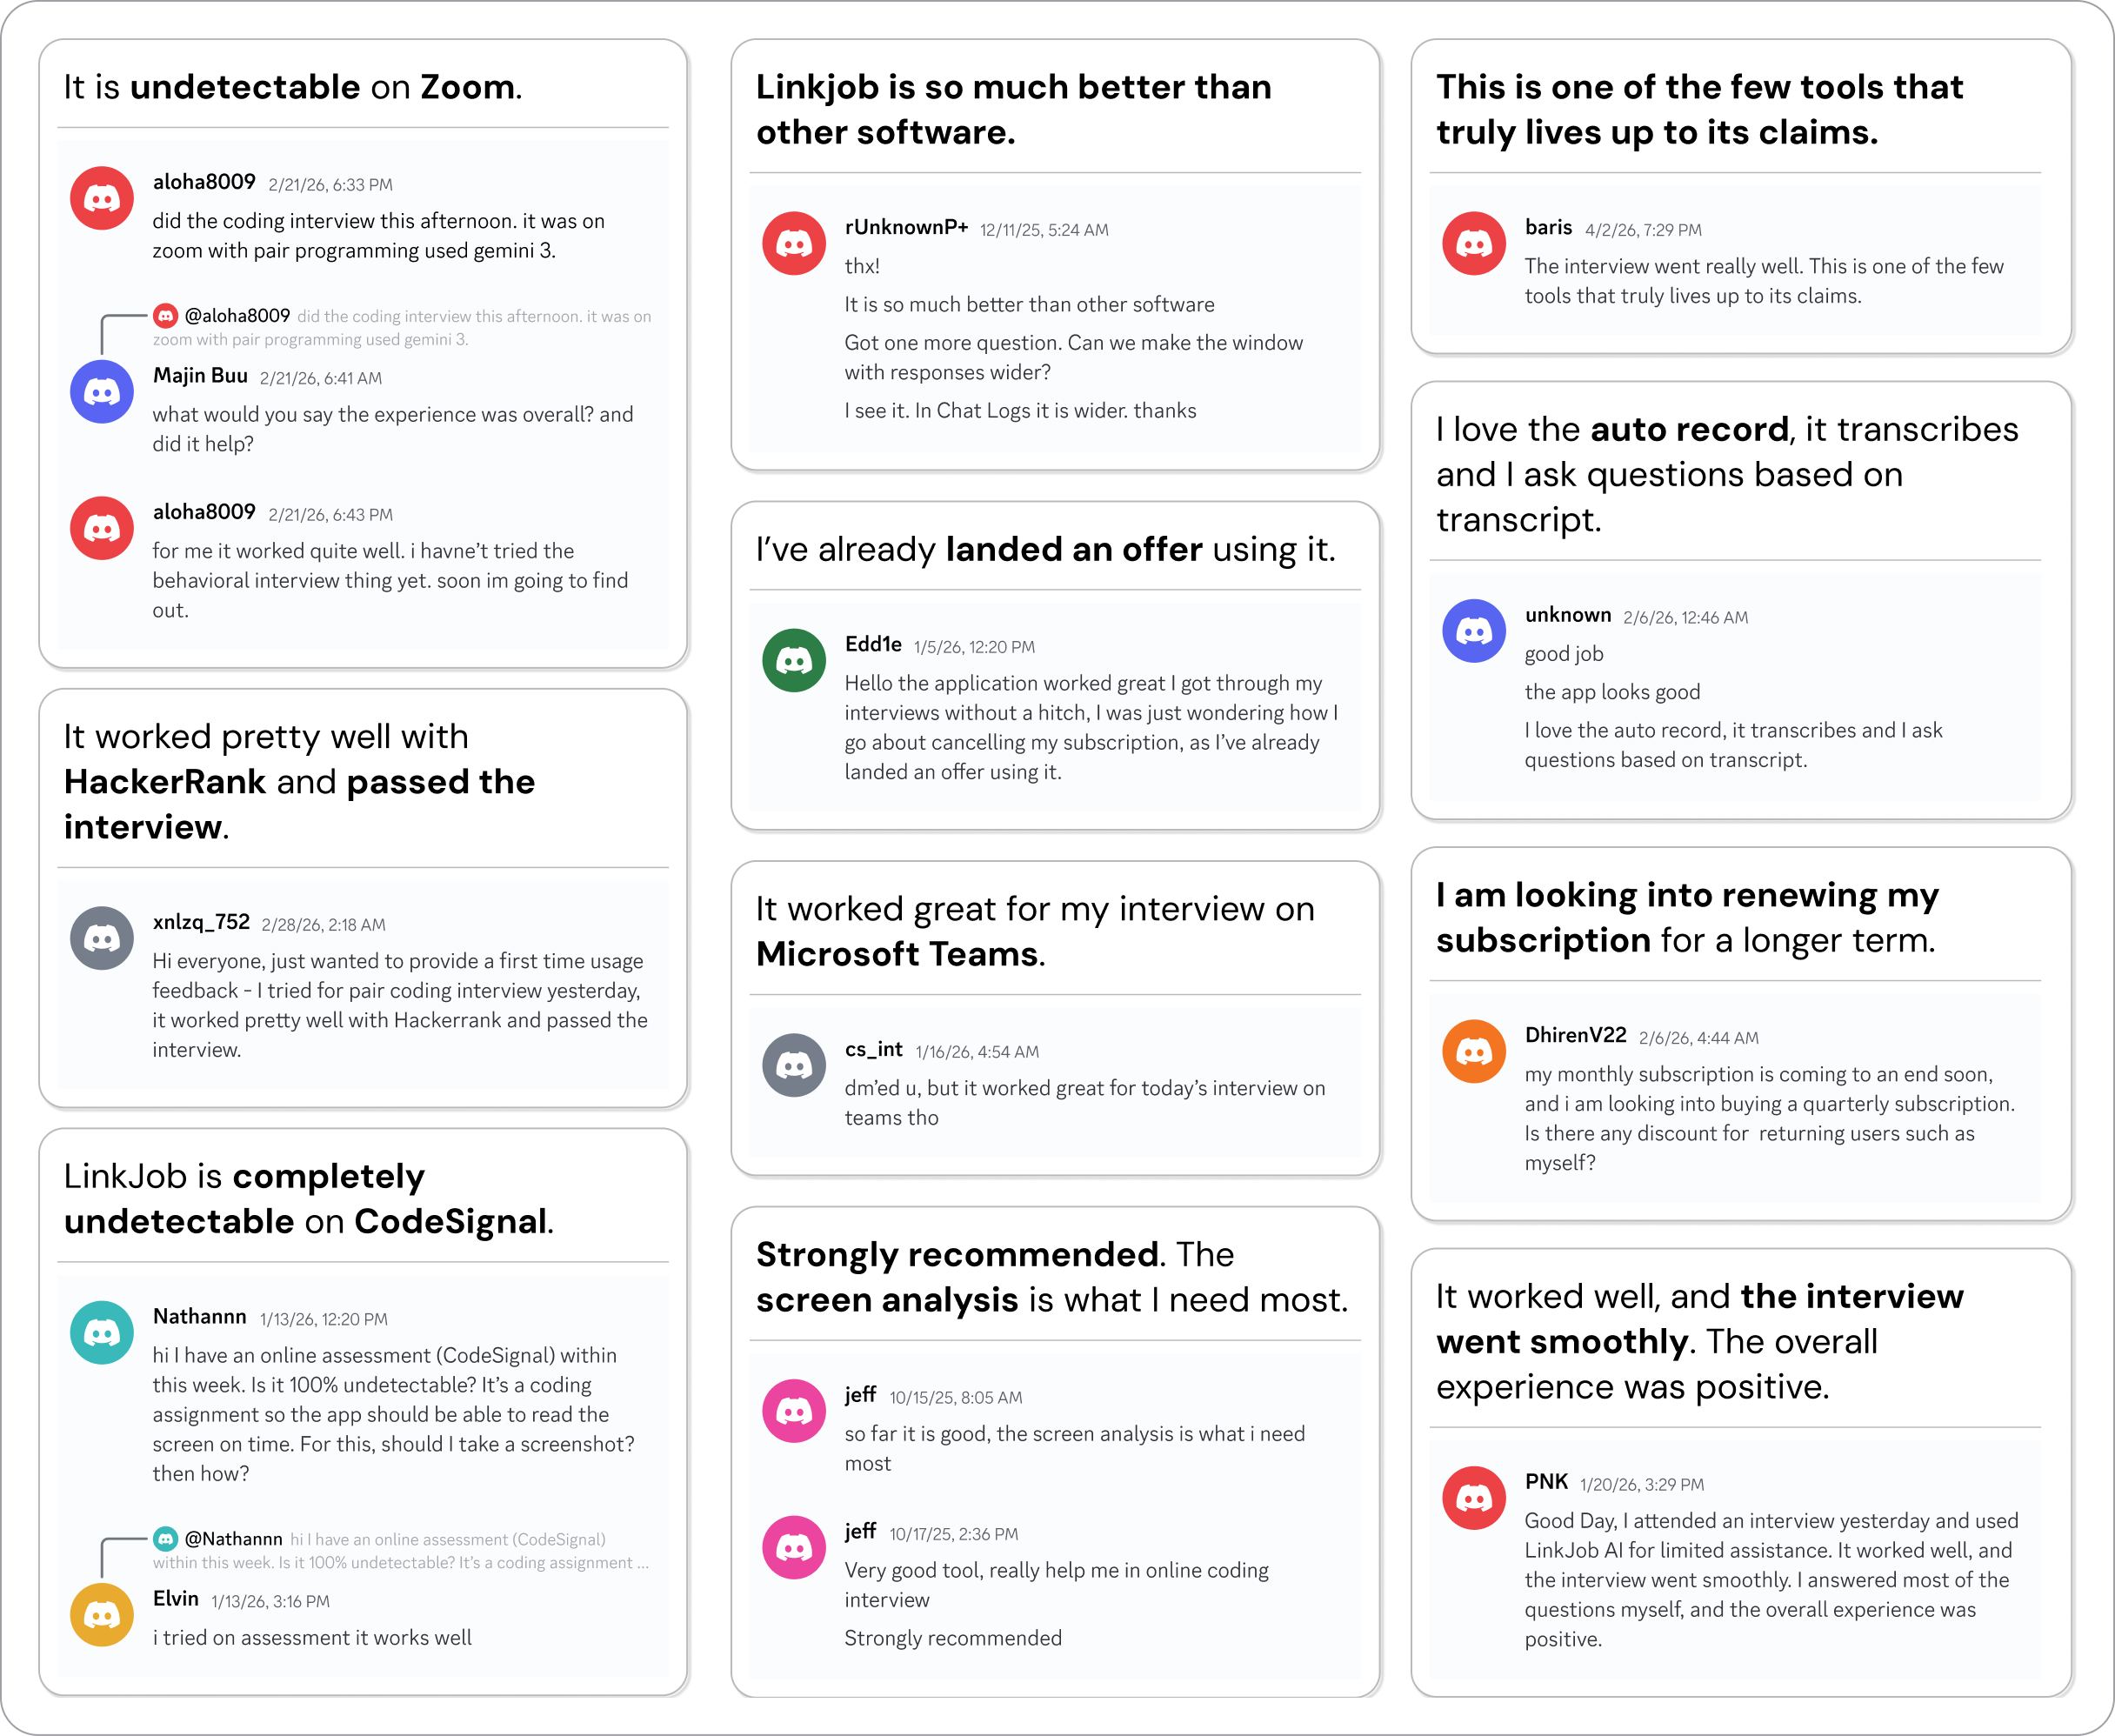
Smoother interviews, coding challenges cleared, and job offers landed. See how users describe their experience with Linkjob AI—in their own words.